
September 16, 2026
Evaluation of Generation-Augmented Retrieval (Rag) Methodologies in the Construction of Generative Agents
Matheus Pinheiro Leopoldino; Anna Carolina Martins
DOI: 10.22167/2675-6528-202602280
Article derived from a Final Course Work (TCC), with content based on the student’s original work and adapted to the editorial format of the Revista E&S with the support of the ResumeAI tool, an artificial intelligence solution developed by the Pecege Institute for textual synthesis and organization.
Summary
The recent advancement of large language models has boosted the use of generative agents in corporate contexts, but limitations in factual fidelity and reliance on generic knowledge have persisted. Retrieval-Augmented Generation (RAG) architectures have emerged as a solution to integrate external knowledge bases. The study comparatively evaluated different RAG methodologies applied to the construction of generative agents for automated FAQ handling. To this end, five distinct RAG architectures – classic, with re-ranker, multi-hop, hierarchical, and agent-based – were implemented on a common knowledge base and evaluated under controlled conditions. The evaluation considered metrics of contextual fidelity, response relevance, latency, and token usage, using automated judgments through the LLM-as-a-judge approach. The results highlighted structural trade-offs between response quality, computational cost, and response time, indicating the absence of a universally superior approach. Notably, the hierarchical method offered the best compromise between performance and computational cost. As a contribution, the research provided a systematic comparative analysis that supports technical and architectural decisions in the design of RAG-based generative agents for business applications.
Keywords: Architecture; LLM; LLM-as-a-Judge; Retrieval.
1. Introduction
The evolution of Large Language Models (LLMs) has transformed human interaction with computational systems, driving the development of generative agents in various contexts, notably in the corporate environment. These agents are designed to simulate human textual interaction and execute behaviors directed towards specific objectives, utilizing complementary tools that grant them autonomy (Park et al., 2023). This capability has generated significant value for companies and individuals (Godbole et al., 2024; Yu et al., 2025; Manda, 2025; Borishetty et al., 2025).
In the customer service sector, the implementation of generative agents based on LLMs has been adopted as an effective alternative to optimize operations. A case study at a company with five thousand employees demonstrated a 37.5% reduction in the number of support requests after the introduction of a customer service solution based on generative artificial intelligence (Al-Osaimi et al., 2025). This application aims to decrease overflows to level one human teams, while simultaneously enhancing the quality and consistency of responses provided to users.
However, despite the potential, LLMs face significant challenges, especially in specific domains. One of the main problems lies in the factual fidelity of the responses and the dependence on generic knowledge obtained during pre-training, which can result in outdated or inaccurate information for business contexts that require specific internal knowledge (Genesis, 2025). This limitation prevents the models from providing accurate answers to questions that demand corporate or specialized data.
To overcome these shortcomings, Retrieval-Augmented Generation (RAG) architectures emerge as a promising solution. RAG combines search mechanisms with generative models, allowing the integration of external knowledge bases into the response generation process. This approach improves the factual grounding of responses and facilitates adaptation to specific knowledge bases, which is crucial in support environments with a high volume of questions that depend on a pre-established internal knowledge base (Gupta et al., 2024; Genesis, 2025).
Despite the effectiveness of RAG, building these systems involves choosing among various strategies, each with its own trade-offs in terms of accuracy, latency, and computational cost (Genesis and Keane, 2025; Brontes et al., 2025). The proliferation of new techniques and the scarcity of systematic comparative evaluations make it difficult to make informed architectural decisions for building generative agents. This gap in the scientific framework hinders the selection of the most suitable methodology for different application scenarios.
Given this scenario, the present research is justified by the need for a systematic comparative analysis that can support technical and architectural decisions in the design of RAG-based generative agents for business applications. Thus, the objective of the work is to evaluate the performance of different RAG methodologies applied to the construction of generative agents focused on automated customer service for frequently asked questions, comparing them based on the metrics faithfulness, latency in response generation, token usage, answer relevancy, and context relevancy, seeking to find methodologies that offer a better cost-benefit regarding technical robustness, operational cost, and quality of the final answers.
2. Material and Methods
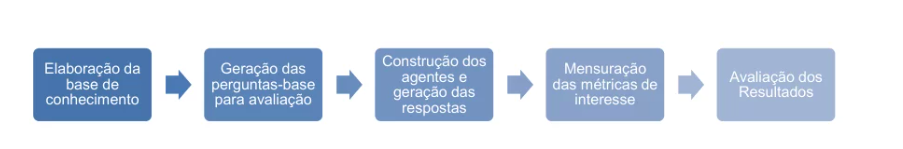
The adopted research is applied and exploratory in nature, aiming to understand the functioning of different Generative Augmented Retrieval (RAG) methodologies through the construction of an algorithm. The study was divided into four main phases, as illustrated in Figure 1, with steps performed multiple times to compare RAG methodologies.
Figure 1. Steps of the methodological process for evaluating multiple RAG methodologies.
Source: Original research results
The research execution used a computational environment configured in Python, employing libraries such as CrewAI for the construction of generative agents and reproducibility of experiments. The libraries used and their roles are detailed in Table 1.
Table 1. Libraries used in the study
| Library | Version | Role in the study |
|---|---|---|
| openai | 1.0.0 | Interface with models (LLM and “embeddings”) provided by OpenAI via API. |
| human-related | 0.34.0 | Interface with LLM models provided by Anthropic via API. |
| crewai | 0.28.0 | “Agentic framework” used. |
| faiss-cpu | 1.7.4 | Vector indexing and search of the knowledge base “embeddings”. |
| numpy | 1.24 | Manipulation and storage of the numerical vectors generated by the “embeddings” model. |
| pandas | 2.0 | Reading, organization, and storage of experimental data. |
Source: Original research results
The study, which deals with unstructured data (texts), performed qualitative analyses scaled through language models, used both in the generation and automated evaluation of responses.
The knowledge base was built from the Manual of Instructions and Norms for ESALQ/USP Course Conclusion Works, in PDF format. From this document, 200 textual excerpts were extracted and segmented using the multimodal model openai-gpt-5.2, via the “web” platform, with standardized instructions to identify semantically coherent textual units and mitigate biases. The “prompt” included a combined question and answer return pattern.
After extraction, the excerpts were reclassified by an LLM into unsupervised induced categories, such as Concept, Process, Evaluation, Guidance, Research Project, Methodology, Ethics, Formatting, References, Figures/tables, Analysis, Conclusion, Preliminary results, Final thesis, Defense, Submission, Pre-textual elements, Post-textual elements, Appendices, Citations, Post-defense, Exams, Acknowledgement, and Resources.
The knowledge base content was transformed into numerical vectors (“snippets”) using OpenAI’s text-embedding-3-small model. These vectors were converted to “float32” and organized into a NumPy “array”.
A vector index was built with FAISS, using the IndexFlatL2 structure for Euclidean distance (L2) similarity. The index was populated with the generated “embeddings” and persisted to disk, maintaining the mapping between index position and textual record.
The base vector retrieval, common to all evaluated methodologies, was implemented deterministically. Queries were converted into numerical vectors by the same model and searched in the FAISS index, returning the top 5 results (“snippets”) by “Nearest Neighbor Search”.
To evaluate the RAG methodologies, 200 questions were generated by the gemini-3-flash model (via the “web” platform), different from the knowledge base creation model to avoid biases. The questions were equally divided into four groups, according to Table 2, to evaluate different levels of dependency on the retrieval mechanism.
Table 2. Classifications of questions created for evaluation
| Classification | Definition | Example |
|---|---|---|
| Totally related – “single-snippet” | Questions whose answer can be fully obtained from a single passage retrieved from the knowledge base. | Can the TCC be carried out in a group? |
| Fully related – “multi-snippet” | Questions whose answer requires the combination of two or more passages retrieved from the knowledge base. | What is the weight of the TCC in the final average and how does failing it affect obtaining the degree? |
| Partially related | Questions related to the content of the base, but that demand additional knowledge not present in the retrieved excerpts. | Is there a limit to how many times I can change advisors? |
| Unrelated | Questions unrelated to the content of the knowledge base, not answerable by the RAG system. | How to learn to play guitar alone on the internet? |
Source: Original research results
Multiple agents were built using the CrewAI “framework” to implement and compare five RAG strategies: Classic, Re-ranking, Multihop, Hierarchical, and Agentic, as detailed in Table 3. For comparability, parameters such as temperature (0), maximum number of retrieved passages (5), and language model (openai-gpt-40-mini) were kept constant, as were equivalent “prompts”.
Table 3. RAG strategies for response generation used
| Strategy | Definition |
|---|---|
| Classic | Relevant passages are retrieved by vector search and provided directly as context for a language model to generate the answer. |
| Re-ranking | Segments initially retrieved by vector search undergo an additional semantic re-evaluation step to select the most relevant contexts before generating the response. |
| Multi-hop | System performs multiple retrieval steps, formulating successive intermediate questions to gather complementary information before producing the final answer. |
| Hierarchical | Organizes the knowledge base into thematic levels and restricts vector search to the topic groups most relevant to the question, refining the scope of retrieval. |
| Agentic | Multiple specialized agents cooperate with each other, distributing tasks such as question refinement, context retrieval, and answer synthesis in a collaborative reasoning flow. |
Source: Original research results
The Classic RAG approach directly integrated vector retrieval with the generation model. Semantically close snippets were selected, organized into context blocks, and concatenated for the language model to generate the response. A single agent orchestrated the vector search and response generation.
In RAG with Re-ranking, an intermediate step was added. After the initial vector search, the snippets were submitted to a semantic re-evaluation by a language model (“cross-encoder”) to select the three most relevant ones, which composed the final context. A single agent managed the search and re-ranking.
The “multi-hop” RAG used an iterative retrieval mechanism. The language model analyzed the retrieved passages and, if necessary, formulated intermediate questions to obtain complementary information. This process could be repeated for up to 3 interactions, building a progressive context from dispersed information.
The Hierarchical approach structured the knowledge base into thematic groups. For each question, a language model classified the most likely topic, restricting the vector search to the excerpts within that thematic group. The resulting excerpts were then organized and provided to the generative model.
The Agent-based RAG expanded the architecture to a multi-agent system in the CrewAI framework. Specialized agents took on roles such as reformulating the original question, searching and selecting relevant snippets, and synthesizing the final answer. The sequential and coordinated interaction between agents simulated a collaborative reasoning flow.
During execution, data such as context sent, “token” count, and latency were stored. The decision, retrieval, and re-ranking steps were tracked by “debug” “logs” to ensure transparency and reproducibility. Agent flows were executed in isolation, with memory release mechanisms to prevent “state leakage”.
The evaluation of the methodologies considered five main metrics: “faithfulness” (fidelity of the response to the context), “answer relevancy” (adequacy of the response to the question), “context relevancy” (quality of the retrieved snippets), latency (processing time), and “tokens” usage (computational consumption). The first three metrics evaluate semantic and informational quality, while the latter two reflect performance and cost.
The quality metrics (“faithfulness”, “answer relevancy”, “context relevancy”) were calculated using the “LLM-as-a-judge” approach, employing the claude-haiku-4-5-20251001 model, configured with zero temperature for deterministic and reproducible judgments, in order to reduce biases. The evaluation “prompts” defined explicit criteria for normalized scores between 0 and 1, accompanied by textual justifications.
Operational metrics for latency and “token” usage were measured directly by the execution “runner”, using system clock “timestamps” for latency and “token” consumption as a computational cost “proxy”. A “retry” mechanism was implemented for evaluator calls, with up to three additional attempts and exponential “backoff” (1, 2, and 4 seconds) in case of transient errors.
3. Results and Discussion
The results for the faithfulness metric indicated a progressive degradation in the fidelity of the responses as the complexity of the questions increased. Questions fully related and supported by a single snippet showed the highest levels of factual adherence, followed by those requiring multiple snippets, partially related questions, and finally, unrelated questions. This pattern, detailed in Table 4, suggests that as tasks demand greater semantic integration capacity or inference beyond explicitly available knowledge, the probability of factual deviations in the responses generated by the evaluated systems increases. Although many scenarios showed consistent values between the first (Q1) and third quartile (Q3), scenarios with high variation and where responses could be generated from the available knowledge base may represent risks for corporate implementation and should be analyzed on a case-by-case basis.
Table 4. Results for the LLM-as-a-judge metric “faithfulness”
| RAG Method | Group | Average | Q1 | Median | Q3 |
|---|---|---|---|---|---|
| Agentic | Unrelated | 0.7 | 0.3 | 1.0 | 1.0 |
| Classic | Unrelated | 1.0 | 1.0 | 1.0 | 1.0 |
| Hierarchical | Unrelated | 1.0 | 1.0 | 1.0 | 1.0 |
| Multi-hop | Unrelated | 0.5 | 0.0 | 0.5 | 1.0 |
| Re-ranking | Unrelated | 1.0 | 1.0 | 1.0 | 1.0 |
| Agentic | Partially related | 0.8 | 0.5 | 1.0 | 1.0 |
| Classic | Partially related | 0.9 | 0.6 | 1.0 | 1.0 |
| Hierarchical | Partially related | 0.9 | 1.0 | 1.0 | 1.0 |
| Multi-hop | Partially related | 0.8 | 0.5 | 1.0 | 1.0 |
| Re-ranking | Partially related | 0.8 | 0.5 | 1.0 | 1.0 |
| Agentic | multiple snippets | 0.7 | 0.5 | 0.5 | 1.0 |
| Classic | multiple snippets | 0.7 | 0.5 | 0.5 | 1.0 |
| Hierarchical | multiple snippets | 0.8 | 0.5 | 0.8 | 1.0 |
| Multi-hop | multiple snippets | 0.6 | 0.5 | 0.5 | 0.5 |
| Re-ranking | multiple snippets | 0.7 | 0.5 | 0.5 | 1.0 |
| Agentic | “one snippet” | 1.0 | 1.0 | 1.0 | 1.0 |
| Classic | “one snippet” | 1.0 | 1.0 | 1.0 | 1.0 |
| Hierarchical | “one snippet” | 0.9 | 1.0 | 1.0 | 1.0 |
| Multi-hop | “one snippet” | 1.0 | 1.0 | 1.0 | 1.0 |
| Re-ranking | “one snippet” | 1.0 | 1.0 | 1.0 | 1.0 |
Source: Original research results.
This pattern of fidelity degradation was consistent across different RAG methodologies, but with varying intensities. More complex approaches, such as agentic and multihop methodologies, showed a greater propensity for hallucination. In the multihop approach, this can be attributed to the successive chaining of intermediate queries and answers, which tends to introduce additional noise and increase the chance of generating content not strictly grounded. The agentic methodology, in turn, exhibited greater variability in faithfulness scores, possibly due to the autonomy of the agents and the division of cognitive responsibilities, which can lead to more elaborate answers even with partial or non-existent grounding. It is crucial to evaluate hallucination cases considering the risk associated with the use case, distinguishing between answers with no logical content relation and those that, although not grounded in the internal base, may be correct based on world knowledge. The study observed the second type of hallucination. In contrast, the hierarchical approach demonstrated greater robustness in the faithfulness metric, which is associated with the strong contextual restriction mechanism imposed by the hierarchical organization of documents, limiting exposure to marginal contexts.
The joint analysis of faithfulness and answer relevancy metrics, presented in Table 5, revealed a significant trade-off between factual fidelity and perceived usefulness of the responses. Methodologies with a higher propensity for hallucination frequently exhibited higher answer relevancy scores. This suggests that the freedom to extrapolate beyond explicitly retrieved knowledge, while increasing the risk of inaccuracy, can generate more useful responses, especially when the knowledge base does not contain information directly applicable to the proposed question. This finding highlights the importance of maintaining knowledge bases in RAG systems and indicates an inversely proportional relationship between base coverage and the need for external knowledge by retrieval agents.
Table 5. Results for the LLM-as-a-judge metric “answer relevancy”
| RAG Method | Group | Average | Q1 | Median | Q3 |
|---|---|---|---|---|---|
| Agentic | Unrelated | 0,5 | 0,0 | 0,3 | 1,0 |
| Classic | Unrelated | 0,0 | 0,0 | 0,0 | 0,0 |
| Hierarchical | Unrelated | 0,0 | 0,0 | 0,0 | 0,0 |
| Multi-hop | Unrelated | 0,7 | 0,1 | 1,0 | 1,0 |
| Re-ranking | Unrelated | 0,0 | 0,0 | 0,0 | 0,0 |
| Agentic | Partially related | 0,5 | 0,5 | 0,5 | 0,5 |
| Classic | Partially related | 0,6 | 0,5 | 0,5 | 0,9 |
| Hierarchical | Partially related | 0,5 | 0,5 | 0,5 | 0,5 |
| Multi-hop | Partially related | 0,4 | 0,1 | 0,5 | 0,5 |
| Re-ranking | Partially related | 0,6 | 0,5 | 0,5 | 0,9 |
| Agentic | multiple snippets | 0,9 | 0,6 | 1,0 | 1,0 |
| Classic | multiple snippets | 0,8 | 0,6 | 0,8 | 0,9 |
| Hierarchical | multiple snippets | 0,8 | 0,8 | 0,9 | 1,0 |
| Multi-hop | multiple snippets | 0,9 | 1,0 | 1,0 | 1,0 |
| Re-ranking | multiple snippets | 0,8 | 0,8 | 0,9 | 1,0 |
| Agentic | “one snippet” | 1,0 | 1,0 | 1,0 | 1,0 |
| Classic | “one snippet” | 1,0 | 1,0 | 1,0 | 1,0 |
| Hierarchical | “one snippet” | 0,9 | 1,0 | 1,0 | 1,0 |
| Multi-hop | “one snippet” | 1,0 | 1,0 | 1,0 | 1,0 |
| Re-ranking | “one snippet” | 1,0 | 1,0 | 1,0 | 1,0 |
Source: Original research results.
The effect of higher relevance with lower fidelity was notable in the set of unrelated questions, where the multihop approach presented a significant proportion of useful answers, even without direct factual support from the knowledge base. In these cases, high answer relevancy resulted from the use of general knowledge or implicit inferences from the model. This demonstrates that perceived utility and factual fidelity are complementary dimensions, not necessarily aligned. The context relevancy metric, presented in Table 6, revealed a distinct behavior from the previous metrics. Although there was a progressive degradation of the relevance of the retrieved snippets with increasing question complexity, no significant differences were observed between the evaluated methodologies. This suggests that the retrieval mechanisms, in the studied implementations, converged to semantically similar context sets, regardless of the RAG architecture used.
Table 6. Results for the LLM-as-a-judge metric “context relevancy”
| RAG Method | Group | Average | Q1 | Median | Q3 |
|---|---|---|---|---|---|
| Agentic | Unrelated | 0,0 | 0,0 | 0,0 | 0,0 |
| Classic | Unrelated | 0,0 | 0,0 | 0,0 | 0,0 |
| Hierarchical | Unrelated | 0,0 | 0,0 | 0,0 | 0,0 |
| Multi-hop | Unrelated | 0,0 | 0,0 | 0,0 | 0,0 |
| Re-ranking | Unrelated | 0,0 | 0,0 | 0,0 | 0,0 |
| Agentic | Partially related | 0,3 | 0,0 | 0,3 | 0,5 |
| Classic | Partially related | 0,3 | 0,0 | 0,3 | 0,5 |
| Hierarchical | Partially related | 0,3 | 0,0 | 0,3 | 0,5 |
| Multi-hop | Partially related | 0,3 | 0,0 | 0,3 | 0,5 |
| Re-ranking | Partially related | 0,3 | 0,0 | 0,3 | 0,5 |
| Agentic | multiple snippets | 0,6 | 0,5 | 0,5 | 0,8 |
| Classic | multiple snippets | 0,6 | 0,5 | 0,5 | 0,8 |
| Hierarchical | multiple snippets | 0,6 | 0,5 | 0,5 | 0,8 |
| Multi-hop | multiple snippets | 0,6 | 0,5 | 0,6 | 0,8 |
| Re-ranking | multiple snippets | 0,6 | 0,5 | 0,5 | 0,8 |
| Agentic | “one snippet” | 0,9 | 0,9 | 1,0 | 1,0 |
| Classic | “one snippet” | 0,9 | 0,9 | 1,0 | 1,0 |
| Hierarchical | “one snippet” | 0,9 | 0,9 | 1,0 | 1,0 |
| Multi-hop | “one snippet” | 0,9 | 0,9 | 1,0 | 1,0 |
| Re-ranking | “one snippet” | 0,9 | 0,9 | 1,0 | 1,0 |
Source: Original research results.
The absence of relevant differentiation in the context relevancy metric does not imply that all methodologies are equally effective in terms of context retrieval, but suggests that the applied strategies may not have been sufficiently distinct or necessary to produce measurable separations. Three factors may have contributed to this scenario: the structure of the knowledge base, which was a highly delimited manual of norms, favoring precise retrievals; the nature of the generated questions, which, despite being from another language model, maintained a high semantic relationship with the base for fully related questions; and the bottleneck in the top-K of five retrieved snippets, which may have limited the deepening capacity of techniques such as multihop and re-ranking, focused on extensive knowledge bases. This result suggests the need for future investigations with more sophisticated question generation and retrieval techniques.
Regarding latency, the results, detailed in Table 7, reflected the inherent computational complexity of each methodology. The classical method demonstrated the lowest response times due to its architectural simplicity and fewer steps, making it ideal for simple questions where latency is a critical factor. On the other hand, more elaborate methodologies, such as re-ranking, presented substantially higher latencies, even for low-complexity questions. This indicates that the additional computational cost introduced by intermediate steps may not be offset in all scenarios, suggesting the suitability of different RAG methodologies for specific types of questions and the possibility of hybrid pipelines in production environments.
Table 7. Results for the latency metric in response generation
| RAG Method | Group | Average | Q1 | Median | Q3 |
|---|---|---|---|---|---|
| Agentic | Unrelated | 10,3 | 7,7 | 8,4 | 12,4 |
| Classic | Unrelated | 3,2 | 2,5 | 2,6 | 3,7 |
| Hierarchical | Unrelated | 4,2 | 3,5 | 3,9 | 5,0 |
| Multi-hop | Unrelated | 9,3 | 6,3 | 8,5 | 12,5 |
| Re-ranking | Unrelated | 17,0 | 8,8 | 14,2 | 15,3 |
| Agentic | Partially related | 7,0 | 5,7 | 6,6 | 7,3 |
| Classic | Partially related | 3,1 | 2,5 | 2,7 | 3,2 |
| Hierarchical | Partially related | 4,3 | 3,3 | 4,0 | 4,9 |
| Multi-hop | Partially related | 6,4 | 5,8 | 6,1 | 6,4 |
| Re-ranking | Partially related | 10,3 | 8,0 | 8,6 | 9,0 |
| Agentic | multiple snippets | 8,4 | 7,8 | 8,3 | 8,9 |
| Classic | multiple snippets | 5,5 | 3,2 | 3,8 | 4,2 |
| Hierarchical | multiple snippets | 4,2 | 3,9 | 4,1 | 4,7 |
| Multi-hop | multiple snippets | 8,3 | 7,8 | 8,2 | 8,8 |
| Re-ranking | multiple snippets | 9,5 | 8,7 | 9,6 | 10,0 |
| Agentic | “one snippet” | 5,9 | 5,3 | 5,4 | 6,0 |
| Classic | “one snippet” | 2,8 | 2,6 | 2,8 | 3,0 |
| Hierarchical | “one snippet” | 3,7 | 3,2 | 3,4 | 4,2 |
| Multi-hop | “one snippet” | 5,5 | 5,3 | 5,4 | 5,5 |
| Re-ranking | “one snippet” | 8,1 | 7,6 | 8,0 | 8,5 |
Source: Original research results.
The analysis of token consumption in the prompt, presented in Table 8, revealed that the multihop and agentic approaches consumed approximately twice as many tokens compared to the other methodologies. This high consumption reflects the need to maintain more extensive interaction histories, multiple intermediate contexts, or additional instructions throughout the generation process. Although associated with the greater cognitive flexibility of these approaches, this increase in operational cost imposes limitations on scalability and economic viability, especially in large-scale applications where latency and cost per request are critical factors in architectural decision-making.
Table 8. Results for the token consumption metric in the prompt
| RAG Method | Group | Average | Q1 | Median | Q3 |
|---|---|---|---|---|---|
| Agentic | Unrelated | 2065 | 1089 | 2010 | 2510 |
| Classic | Unrelated | 783 | 585 | 590 | 1039 |
| Hierarchical | Unrelated | 785 | 688 | 702 | 716 |
| Multi-hop | Unrelated | 2290 | 1216 | 1257 | 3013 |
| Re-ranking | Unrelated | 3596 | 718 | 1517 | 1580 |
| Agentic | Partially related | 1002 | 912 | 931 | 1007 |
| Classic | Partially related | 667 | 593 | 603 | 609 |
| Hierarchical | Partially related | 778 | 694 | 712 | 725 |
| Multi-hop | Partially related | 1247 | 1234 | 1249 | 1258 |
| Re-ranking | Partially related | 903 | 719 | 730 | 750 |
| Agentic | multiple snippets | 1028 | 995 | 1028 | 1057 |
| Classic | multiple snippets | 1851 | 620 | 629 | 647 |
| Hierarchical | multiple snippets | 728 | 705 | 739 | 765 |
| Multi-hop | multiple snippets | 1287 | 1255 | 1301 | 1310 |
| Re-ranking | multiple snippets | 765 | 756 | 761 | 768 |
| Agentic | “one snippet” | 936 | 891 | 914 | 961 |
| Classic | “one snippet” | 597 | 589 | 592 | 597 |
| Hierarchical | “one snippet” | 729 | 602 | 666 | 726 |
| Multi-hop | “one snippet” | 1273 | 1234 | 1261 | 1295 |
| Re-ranking | “one snippet” | 724 | 715 | 718 | 728 |
Source: Original research results.
Figure 1 presents a consolidated analysis of the metrics, revealing the differences in the balance between response quality and computational efficiency among the evaluated methods. The Hierarchical method demonstrated the most balanced performance, combining high levels of faithfulness with relatively high answer relevancy values and good efficiency in token consumption metrics. The Classical method stood out for its low latency, maintaining competitive levels of fidelity and token consumption, making it an efficient alternative when response time is a critical factor. The Agentic method achieved good performance in response quality, particularly in answer relevancy, but showed penalties in computational cost metrics, such as latency and token consumption. The multihop method showed similar performance to the Agentic method in response relevance, but with lower overall computational efficiency. Finally, the Re-ranking method presented more modest results across the analyzed metrics, especially in latency and response relevance. Considering quality and efficiency simultaneously, the consolidated results of the study suggest that the Hierarchical method offers the best trade-off between performance and computational cost in the evaluated context.
Figure 1. Comparative analysis of metrics between the different methods
Source: Original research results.
The results of this study indicated that there is no universally superior RAG methodology across all analyzed dimensions. The different architectures evaluated presented distinct behaviors in the metrics of faithfulness, answer relevancy, context relevancy, latency, and token consumption, revealing the existence of structural trade-offs between factual fidelity, perceived utility, computational cost, and operational performance, especially when evaluated from the perspective of different question styles. More flexible approaches, such as multihop and agentic, tended to produce more relevant answers, especially for questions where the knowledge base did not offer direct support, which can be useful when knowledge coverage is not yet consolidated. However, this gain in answer relevancy came at the cost of a greater propensity for extrapolation not anchored in the retrieved context, manifesting as an increased risk of factual hallucination, higher latency, and significantly greater token consumption. In contrast, more restrictive methodologies, such as the hierarchical approach and the classic method, demonstrated greater control over factual fidelity and better operational performance, albeit with less capacity for extrapolation in complex or loosely related questions. These findings reinforce that quality metrics in RAG systems should not be analyzed in isolation, but rather as complementary dimensions that reflect distinct design objectives. The adoption of RAG systems in production environments should weigh accuracy, utility, cost, latency, and robustness against hallucination, with tolerance for extrapolation being evaluated according to the business context. Hybrid architectures, capable of dynamically selecting the most appropriate methodology for the type of question, may be a promising path to balance these trade-offs.
4. Conclusion
This study comparatively evaluated the performance of different Generative Augmented Retrieval (RAG) methodologies in building generative agents for automated customer service for frequently asked questions. It was found that there is no universally superior approach, but rather structural trade-offs between response quality, computational cost, and operational performance. It was observed that the factual fidelity of the responses degraded with increasing question complexity, being more pronounced in methodologies such as agentic and multi-hop, which also showed a higher propensity for hallucination. In contrast, it was noted that the relevance of the response, especially for questions without direct support in the knowledge base, often increased at the expense of fidelity. The hierarchical methodology demonstrated the best compromise between performance and computational cost, while the classic method stood out for its low latency, being efficient for simpler questions. The main contribution of the research lies in offering a systematic comparative analysis that supports technical and architectural decisions in the design of RAG-based generative agents for business applications.
Despite the findings, the analysis of the context’s relevance did not reveal significant differences between the methodologies, a result that may have been influenced by the highly delimited nature of the knowledge base, the high semantic relationship of the generated questions, and the bottleneck imposed by the limit of five retrieved snippets. Such factors suggest that the retrieval strategies may not have been sufficiently tested in their differentiation capacity. For future investigations, the exploration of more sophisticated question generation and retrieval techniques is recommended, such as deep semantic re-ranking and adaptive query expansion. Adaptive strategies that consider the system’s confidence level and knowledge base coverage are also suggested, aiming to broaden the generalization capacity and reliability of RAG-based generative agents. The implementation of hybrid architectures, capable of dynamically selecting the most appropriate methodology for the type of question, emerges as a promising path to balance the identified trade-offs between accuracy, utility, cost, latency, and robustness against hallucination in productive environments.
Bibliographic References
Al-Osaimi, M; Altuwayrah, A.; Khan, H.; Rahman, Abdul. 2025. Transforming Support Efficiency in Exploration: A Combined GenAI Models Solution for improved Application Support. Disponível em: https://doi.org/10.2118/227054-MS. Acesso em: 25 out. 2025.
Genesis, J. 2025. Retrieval-Augmented Text Generation: Methods, Challenges, and Applications. Disponível em:
Park, J. S.; O’Brien, J. C.; Cai, C. J.; Morris, M. R.; Liang, P.; Bernstein, M. S. 2023. Generative Agents: Interactive Simulacra of Human Behavior. Disponível em: . Acesso em: 30 abr. 2025.
Article originating from the Course Conclusion Work of the Specialization in Data Science and Analytics of the MBA USP/Esalq
To learn more about the course, click here and access the MBX Academy platform