Digital
Innovation
Technology
February 26, 2025
Design patterns in software development: heroes or villains?
Tool reduces code complexity and enables adaptability, but its impacts must be analyzed before implementation
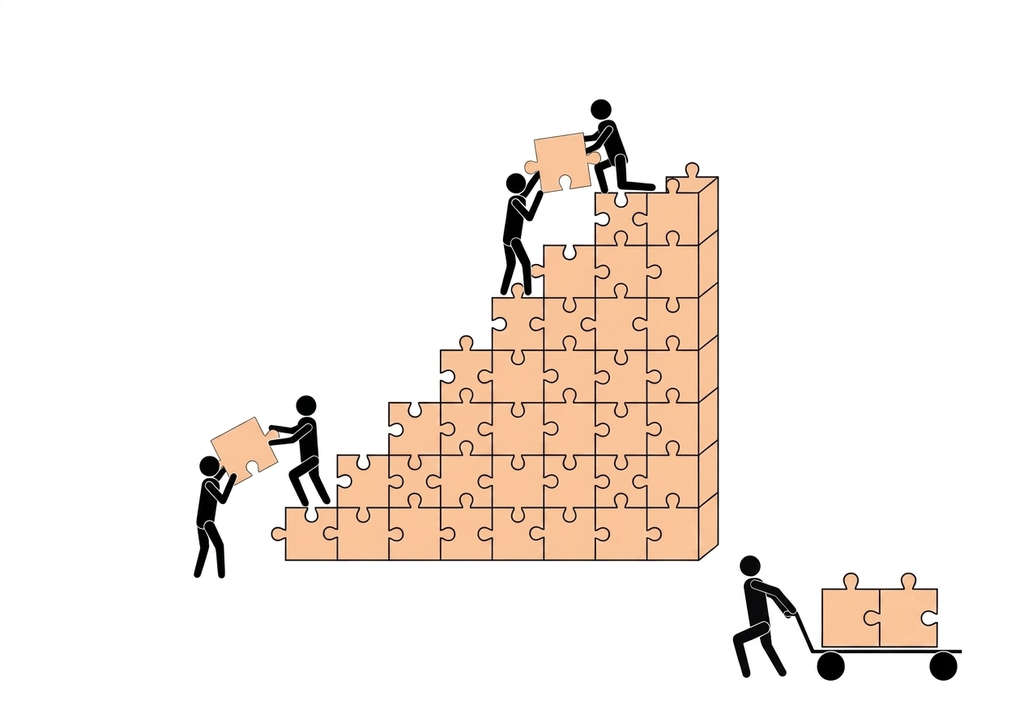
There has been much talk about the use of design patterns in software development and its benefits. However, does the mere use of these patterns really guarantee the solution to the problems they are intended to solve?
The design patterns (or project patterns) are standardized solutions for recurring problems in software projects, offering templates for problem resolution, which makes the code modular and readable.
The expectation is that these standards will be used to facilitate maintenance and optimize software efficiency, improve the quality of code and facilitate communication among development team members. Furthermore, as the tool reduces complexity and provides reuse and adaptability of the code, it also enables productivity gains for the team.
The history of software design patterns is not recent. The idea emerged in architecture before being applied to software development. In 1978, architect Christopher Alexander, along with Sara Ishikawa and Murray Silverstein, cataloged 253 common architectural problems and their solutions in the book “A Pattern Language: Towns, Buildings, Construction”.
Alexander defined that a pattern should have the following characteristics: encapsulation, generality, balance, abstraction, openness, and combinability. These characteristics ended up influencing the development of software design patterns. Later, in 1987, Kent Beck and Ward Cunningham presented the first patterns in the area of computer science, for object-oriented languages.
However, only in 1994, influenced by Alexander’s work, did the popularization of design patterns in software development occur. The release of the book “Design Patterns: Elements of Reusable Object-Oriented Software”, by the “Gang of Four” (GoF) — Erich Gamma, Richard Helm, Ralph Johnson, and John Vlissides —, cataloging 23 design patterns, formalized the use of the tool in the area.
When using design patterns, it is essential to understand each category to choose the most appropriate pattern for the problem to be solved. Therefore, these patterns have been divided into three categories:
- Creational Patterns: allow for creating objects without “tying” the code to specific classes, which require control over the creation process. It’s like ordering a sandwich at Subway: you can choose the bread, the filling, the cheese, and the salad, but you allow the attendant to assemble your sandwich their way. This ensures flexibility (you can choose different types of cheese and sauces), reusability (the same ingredients can be used to produce different sandwiches), and independence (new ingredients can be added without you needing to change how you place your order). Some examples of creational patterns are Builder (a class that creates objects to represent a report with different types of filters, columns, and formatting options), Factory Method (an application can use this pattern to load plugins or extensions, where each plugin is instantiated by a specific factory), and Singleton (can be used for the creation of an object that stores application settings, such as database connection information or user preferences);
- Structural patterns: focus on the construction of complex systems from smaller parts (objects and classes), which can fit together in different ways through the same interface, making them very suitable when high flexibility between parts needs to be ensured. It works like Lego bricks: although there are pieces of different sizes, colors, and purposes, the “fitting pattern” is always the same, allowing many different things to be built with the same pieces. Examples: Adapter (when a system using a payment processing library with a specific interface needs to communicate with another payment library with a different interface) and the Facade pattern (for example, during user registration in the system, the registration interface interacts with a class, which coordinates necessary actions in the validation subsystems, such as database persistence and sending a confirmation email);
- Behavioral patterns: deal with how the objects of a system work together when performing a task. This pattern is useful when flexibility in communication and separation of responsibilities within the system is needed. Think of an orchestra: each musician (object) plays their instrument following their own score (their code) and is responsible for producing different sounds; their behavior is determined by the conductor’s commands (increase volume, change tempo). A very common example is the Observer pattern (a news platform can use this pattern to notify subscribers when a new news item is published); another example is the Command pattern (in applications with graphical interfaces, it is used to represent the actions that can be performed by users through menus and buttons; each menu item or button, such as “Save”, “Open”, “Copy”, and “Paste”, can be associated with a specific Command object, which encapsulates the logic needed to perform the action).
Some studies have shown that projects with teams of larger development tend to use design patterns more frequently. This demonstrates that patterns are used to improve documentation and communication among team members. Furthermore, developers with more experience in programming and design are more likely to use design patterns.
Al-Obeidallah (2021) analyzed the impact of the Adapter design pattern on software maintainability — a quality attribute that indicates how easy the software is to understand and modify. The authors created versions of four software systems without the Adapter pattern, using refactoring techniques, and compared software metrics between the versions with and without the pattern. The analysis of these metrics, correlated with maintainability in previous studies, concluded that the Adapter pattern positively impacts maintainability, reducing indicators such as the number of methods and lines of code and improving cohesion.
Qasim (2021) investigated the impact of using different design patterns on the energy consumption of Android applications. The authors implemented five patterns (Singleton, Facade, Observer, Template, and Abstract Factory) in two open source applications, measuring energy consumption before and after implementation. The results showed that patterns like Observer and Abstract Factory significantly reduced energy consumption, while Singleton, on the other hand, caused an increase.
Excessive engineering
However, the mere use of a design pattern does not guarantee the suggested improvements. In general, research on the impact of design patterns on software quality presents mixed and contradictory results, suggesting that the relationship between design patterns and software quality is complex and influenced by several factors. In fact, there are studies pointing out that some patterns can have a negative impact on software quality.
In parallel, some developers, especially less experienced ones, may try to apply design patterns in situations where simpler solutions would suffice, a problem known as over-engineering.
A negative impact on productivity can also occur if a pattern is poorly utilized, adding excessive complexity and hindering comprehension, which can make modifications to the code more difficult. The implementation of “straightforward” patterns, that is, without adapting them correctly to the context of the application, can generate inefficient solutions.
There is a lack of empirical studies that evaluate the impact of design patterns on software quality, and many studies rely on questionnaires. Thus, it is difficult to analyze and adopt a given design pattern based on research and tools.
How to choose
So, how to choose the most suitable design pattern? This choice should be made taking into account several factors. First, it is necessary to identify exactly what the problem is that one intends to solve through a pattern. Design patterns are solutions for recurring problems, therefore, we must check if the part of the software to be standardized can be identified as a recurring problem.
Only after this step should the intent of each pattern be analyzed, that is, the particular type of problem that each pattern can solve. It is also necessary to consider the consequences and trade-offs that the chosen design pattern will bring to the development and the team. The selected pattern should facilitate communication among team members, not hinder it. Therefore, it is also important to consider the familiarity that the team has with the patterns.
As design patterns are ready-made solutions, it may be necessary to adapt them to the context of the problem, in order to obtain the best relationship between the implementation cost and the benefits that the solution will bring to the project. After all, design patterns were conceived to improve code quality; otherwise, it is better to define the implementation itself, in a simplified way, seeking to guarantee the same quality parameters.
In order to evaluate the impact and quality improvement of the software, some metrics can be calculated before and after a refactoring for the use of a certain design pattern. Some indicators, such as the Maintainability Index, Class Coupling and Cohesion, and even Execution Time, can be relevant to evaluate the benefits of adopting the design pattern in question. However, it can be very difficult to obtain these metrics to perform this more careful evaluation.
Design patterns are not the “silver bullet” for all types of problems. It is important to analyze the situation very well before using them in any software project, to verify if they will bring significant advantages. First, one must evaluate the real need to adopt them in the project.
Often, a good balance can be achieved by developing simpler code, without following a specific pattern, and then refactoring it to use some design pattern, avoiding some implementation issues. Using metrics and the team’s general perception, it will be possible to evaluate whether the use of the pattern after refactoring has improved code quality and brought benefits to everyone.
Regardless of the above, it is important that every developer learns about design patterns, to be able to identify them and contribute more easily to different open source projects, for example. Learning more about these patterns expands the horizons and allows the developer to find new ways to solve problems and propose improvements in existing systems, creating much higher quality software.
| To access the references of this text click here. |
This content was produced by:
Lucas Schiolin Silveira
Graduated in Computer Science from Unesp Rio Claro, holds an MBA in Data Science and Analytics from USP/ESALQ. Works as a developer and technical leader at Skylar. Is a student of AI, Machine Learning and Data Science.
Who wrote this column
Skylar